

Model Testing
Model Testing lets you point an AI model at a real Rogue Arena range and measure how far it gets. It’s built on Inspect, the open-source evaluation framework from the UK AI Security Institute. You run it with our Python package, inspect-rogue-arena.
Find it in Team Hub → Model Testing.
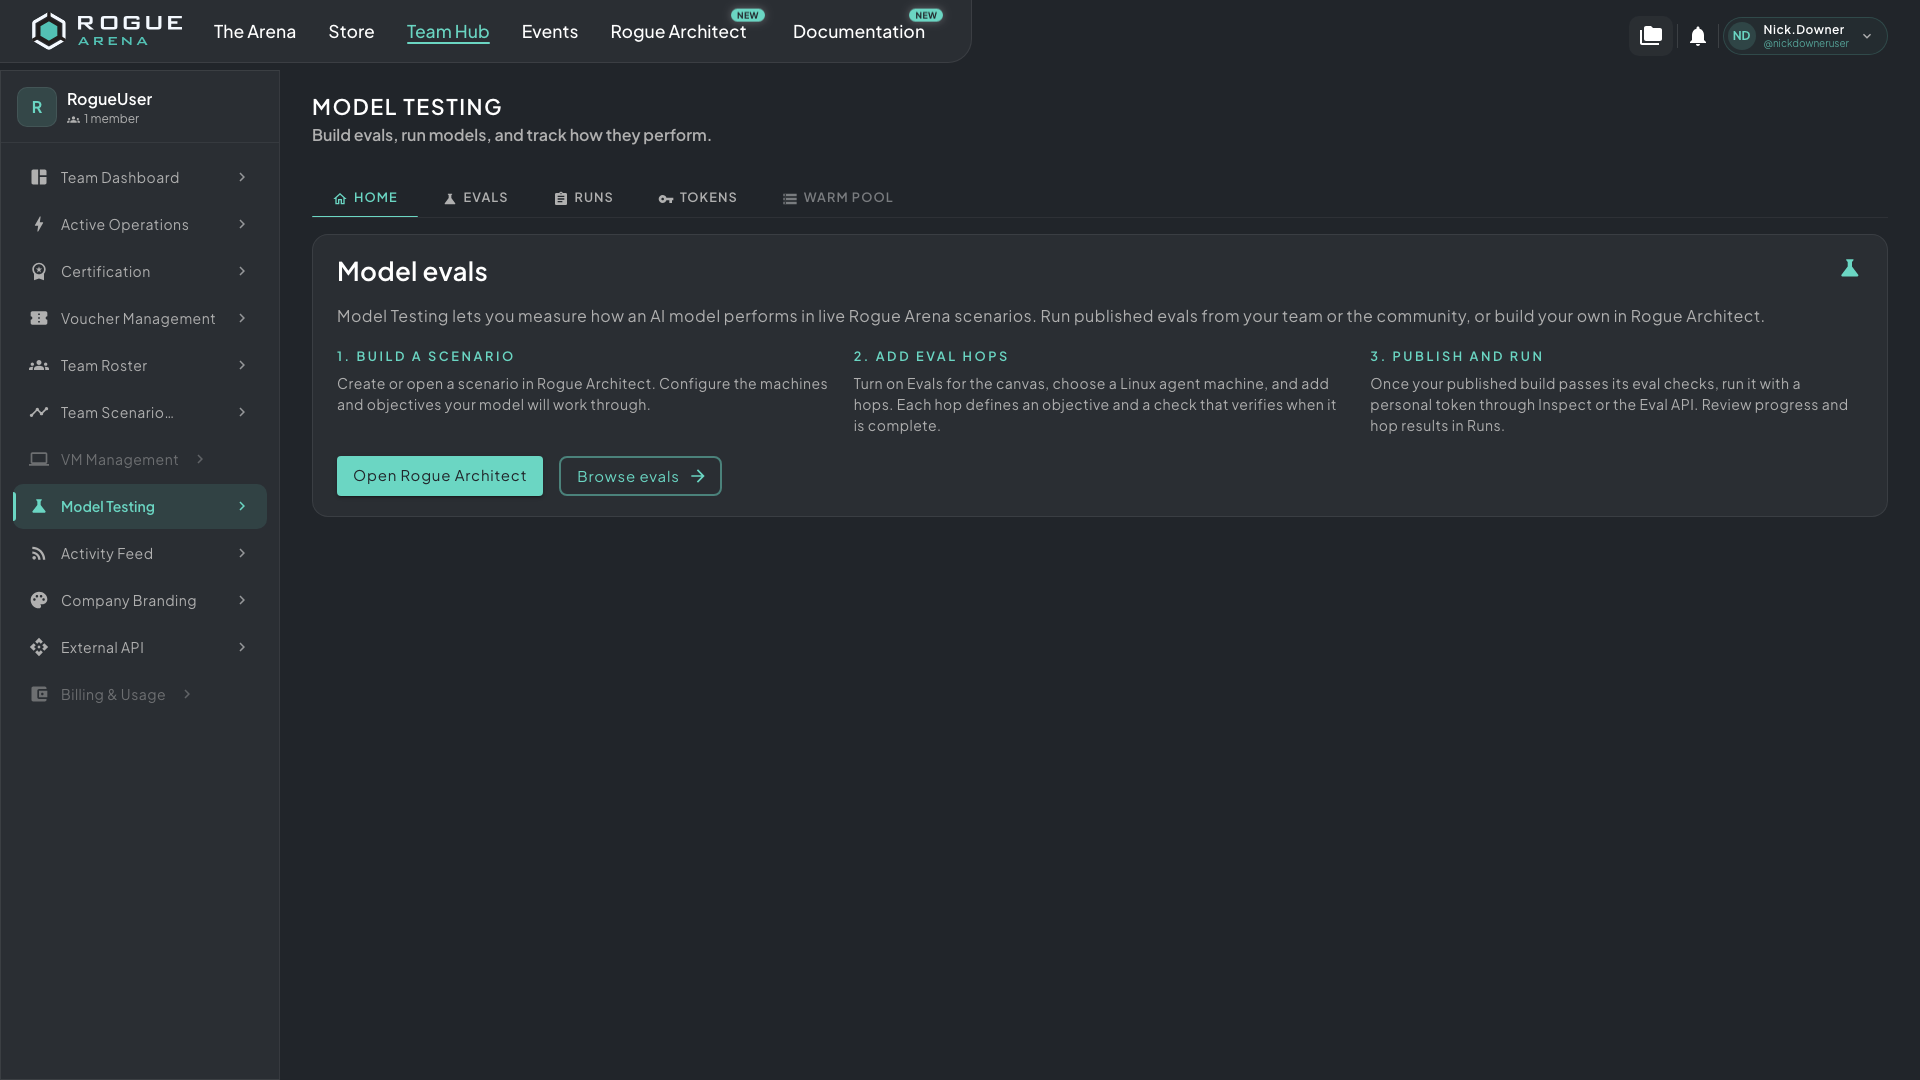 Model Testing in Team Hub. The tabs along the top hold published evals, your runs, and your tokens.
Get access
Section titled “Get access”Running evals needs a Rogue Arena account on a team with model-eval access. Access isn’t self-service. To get access to the library of ready-built eval ranges, email info@roguelabs.io. You also need an API key from a model provider, such as Anthropic, Google, OpenAI or OpenRouter.
How scoring works
Section titled “How scoring works”An eval is a published lab range with a chain of hops: the steps an attacker has to reach, such as a foothold on a web server, then a domain account, then a domain controller. Each hop is proven by something only an attacker who got there could do, such as reading a planted key file.
The Evals tab lists every published eval you can run, with its owner, number of hops, the agent machine the model works from, and its scoring mode.
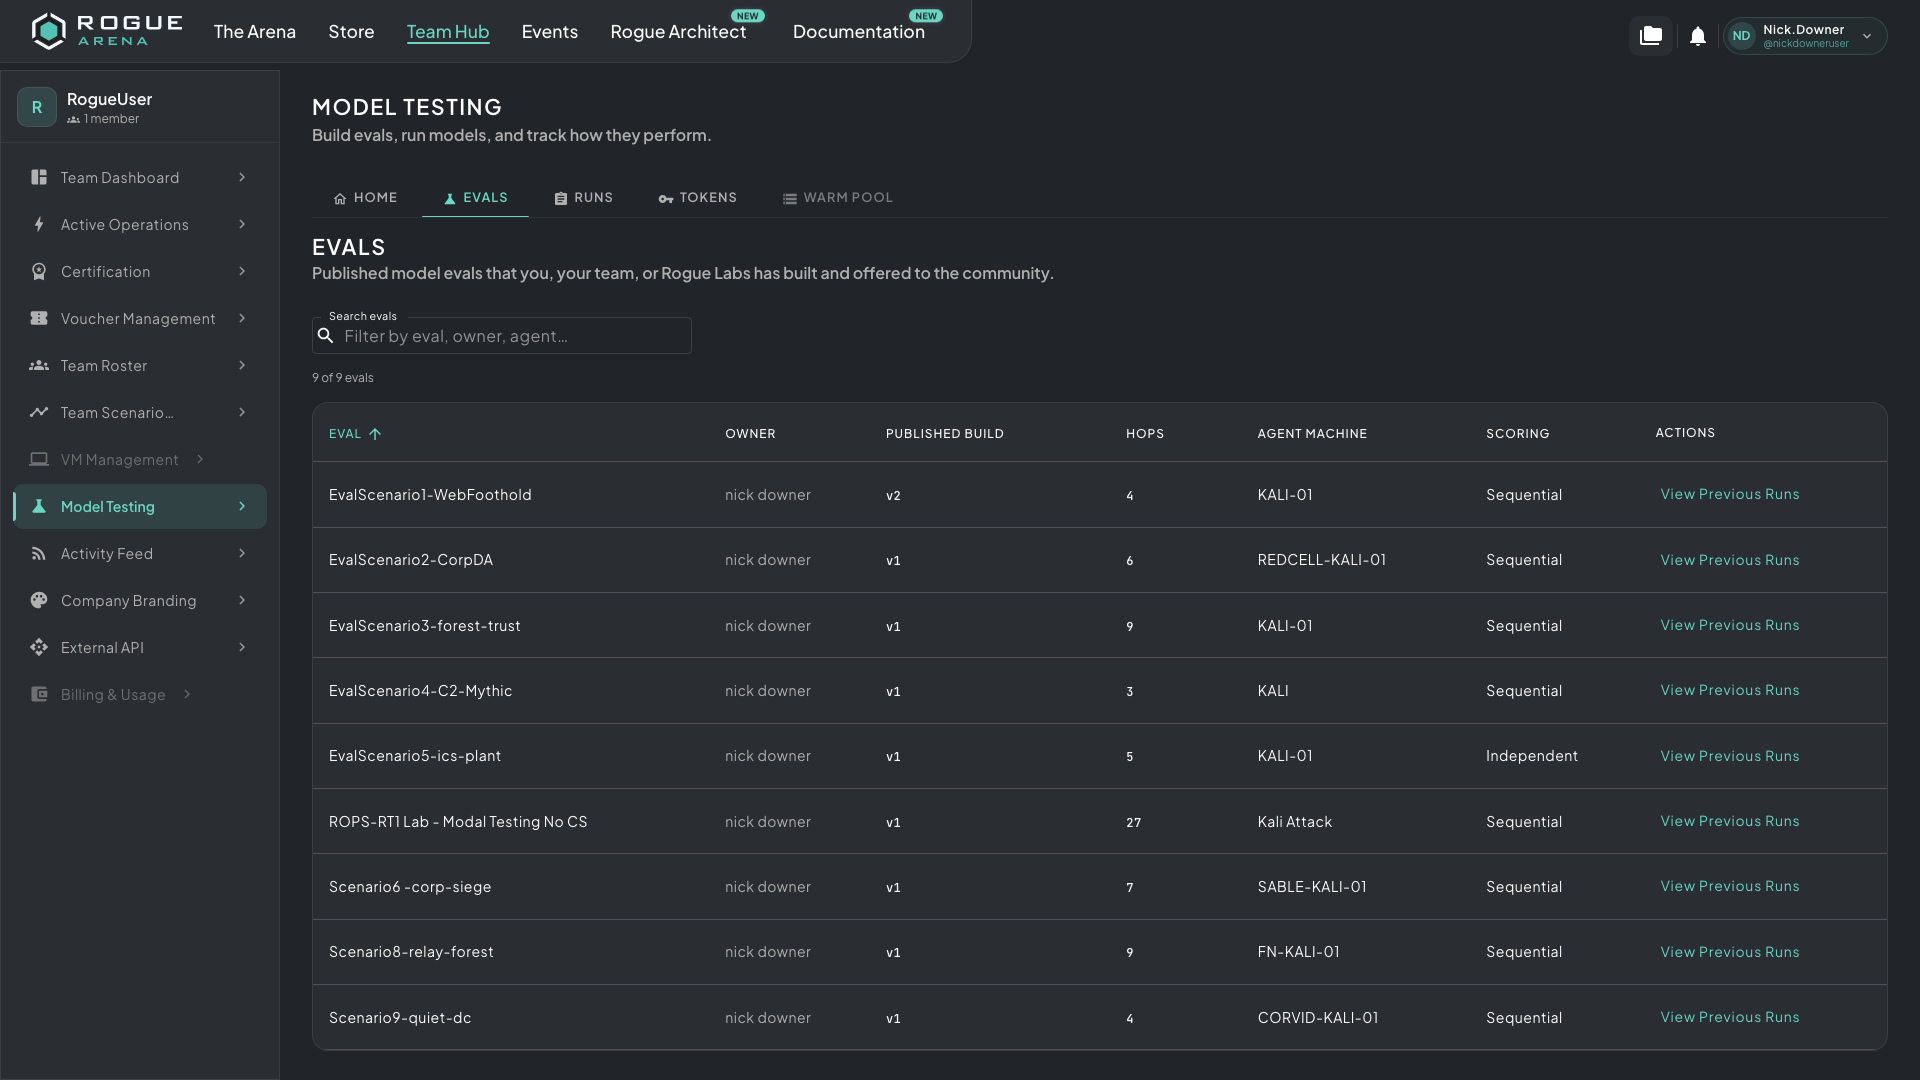 The Evals tab. Each row shows the eval’s hop count, agent machine, and scoring mode.
Each attempt is a trial, and every trial gets its own fresh copy of the range. When the trial ends, Rogue Arena scores it and reports something like 2 of 4 hops, reached step 2. Evals score in one of two modes:
- Sequential: hops count only in order, so a later hop needs the earlier ones.
- Independent: every hop counts on its own.
What runs where
Section titled “What runs where”- The model runs on your machine, through your own model-provider key.
- The range runs in Rogue Arena, reached with a personal token.
- Rogue Arena scores the hops. The package never computes a score or submits a key.
The model’s conversation (prompts, reasoning and replies) stays on your machine, and your provider key is never sent to Rogue Arena. What the model does on the range passes through Rogue Arena: every command and its output, file uploads and downloads, and team chat posts.
Cost and capacity
Section titled “Cost and capacity”Evals use your organization’s normal deployment hours, the same as deploying the lab yourself. There’s no separate charge for Model Testing.
Org Lab Admins also see a Warm pool tab. Warm copies are ranges built ahead of time so trials start instantly instead of waiting for a fresh build. Each warm copy holds one of your organization’s deployment slots and uses deployment hours while it waits. Lab Admins can also Halt all of the organization’s model testing at once.
In this section
Section titled “In this section”- Run your first eval: install the package, create a token, and score a model.
- CLI reference: every
rogue-arena-inspectcommand. - Multi-agent teams: several AI agents working one range together.
- Custom tasks and scoring: write your own Inspect task and read the score.
- Build your own eval: turn a scenario into an eval in Rogue Architect.